
Highlights
Data modeling is no longer just about structuring databases. In the AI era, it is about making business meaning clear, consistent, and machine-readable. This blog explores how conceptual, logical, and physical models support modern cloud architectures, data lakes, analytics, and AI systems. Discover how semantic layers, data contracts, and workload-specific modeling techniques help organizations build reliable, scalable data foundations. From avoiding inconsistent business definitions to enabling trustworthy AI-generated insights, learn why effective data modeling must evolve beyond schemas to embrace governance, quality, lineage, and semantic intelligence. Understand the practices shaping the future of data modeling in 2026.
Consider a retail platform where an AI-powered demand-forecasting agent recommends reducing inventory for a product category that is about to sell out.
The postmortem finds no broken pipeline and no bug in the agent. Instead, the underlying data model contains two different definitions of “active customer”, one in the orders domain and another in returns. The discrepancy has existed for years because no analytical workflow had previously crossed the two definitions.
The AI agent didn’t create the inconsistency. It inherited it. It simply used the available data and produced an answer that looked reasonable because the business meaning behind the data had never been explicitly reconciled.
I’ve spent the better part of my career designing and modernizing data platforms across ISVs and PE-backed software businesses. The pattern repeats constantly: organizations that model once at project kickoff pay for it later, in rework and broken AI initiatives. Organizations that treat modeling as governed, versioned, and revisited build systems that scale without quietly rotting underneath.
Here’s the full picture, what data modeling is, the types and standards that still hold, and what’s genuinely new about doing this well in 2026, told through what that platform team had to unlearn and rebuild.
What Is Data Modeling?
Data modeling is the process of creating a structured representation of an organization’s data, its entities, attributes, relationships, and the rules that govern them. It’s the blueprint underneath every database, every warehouse, and increasingly, every AI system that consumes that data.
Done right, a data model gives teams a shared view of the data; defines entities, relationships and business rules; supports database and analytical design; and provides a foundation that downstream applications, analytics, ML systems and AI solutions can consume consistently.
The important shift is this: the model is no longer only a blueprint for a database. It is increasingly part of the enterprise’s representation of business meaning.
The retail team’s model technically did all three things, for orders. It just never reconciled “active customer” against returns, because nobody had built a shared definition across both. Two locally correct models, globally inconsistent.
What’s Different in the Cloud and AI Era
The original discipline assumed a stable, on, premises database with a known schema. That assumption doesn’t hold anymore.
- Cloud data warehouses decouple storage from compute, changing how you think about normalization, materialization, and cost, a model optimized for an on-prem database isn’t automatically optimized for Snowflake, BigQuery, or Redshift.
- Data lakes and lakehouses bring semi-structured and unstructured data into the modeling conversation. A rigid relational schema doesn’t work when a meaningful share of your data arrives as JSON, logs, or event streams.
- AI and semantic layers now sit directly on top of enterprise data. If the model does not clearly represent business concepts, relationships, metrics and rules, AI systems must infer that context from technical structures and documentation. That inference can fail even when the underlying data is technically correct. A semantic layer addresses this by making business meaning explicit and machine-readable.
The blueprint metaphor still holds. You wouldn’t build on a foundation you haven’t inspected in five years. The retail team hadn’t inspected theirs in three.
Types of Data Models
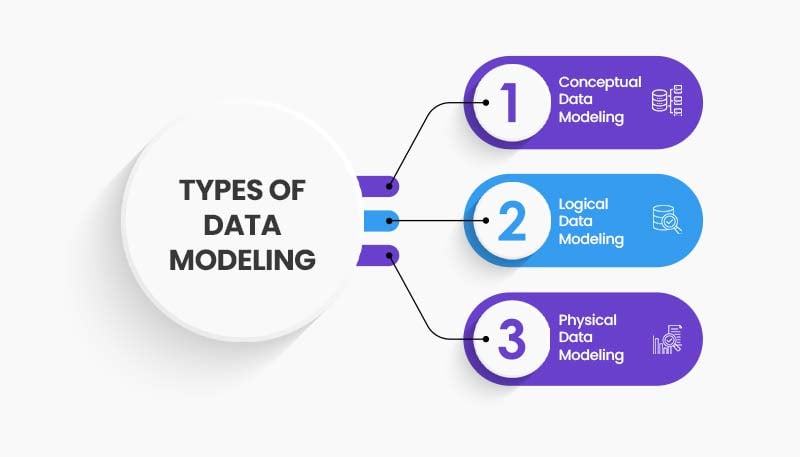
1. Conceptual Data Modeling
Conceptual models stay at the level of business entities, relationships, and attributes, with no technical detail, their job is to align stakeholders on what the data represents before anyone writes DDL. They increasingly need to account for entities that don’t map cleanly to rows and columns, event streams, documents, AI-generated outputs, deciding whether something belongs in structured modeling or in a lake as lighter-weight semi-structured data.
When the retail team rebuilt their model, this was step one: get the orders team and the returns team in the same room and agree, on paper, what “active customer” meant. It took an afternoon. It should have happened three years earlier.
In an AI-enabled environment, this layer becomes even more important because business concepts and not database tables are what ultimately need to be understood by semantic layers and AI systems
2. Logical Data Modeling
Logical models translate the conceptual layer into detailed structures, entities, attributes, relationships, precise enough to design a schema without committing to a specific engine. They now regularly need to represent nested JSON and flexible key-value attributes alongside traditional relational structures.
3. Physical Data Modeling
Physical models implement the logical design against a specific platform, considering storage optimization, indexing, and performance tuning. That platform is now usually a cloud warehouse or lakehouse, where clustering keys, partition strategy, and materialization choices carry direct cost implications in consumption-based pricing.
Data Modeling Techniques
Picking a technique used to be house style. It isn’t anymore, the right technique depends on the workload.
- Relational and normalized modeling remains the right default for transactional systems where consistency matters more than query simplicity.
- Dimensional modeling, star and snowflake schemas, remains the standard for BI workloads where query performance and comprehensibility matter more than storage efficiency.
- Data Vault, built around hubs, links, and satellites, has moved from niche to mainstream for organizations needing full historical traceability and resilience to source-system change. It’s more complex to implement than dimensional modeling but holds up better under frequent schema evolution.
The retail team’s forecasting agent needed a serving model designed around its workload, rather than simply exposing the underlying transactional or analytical structures directly to the agent.
Depending on the use case, that serving model might be dimensional, denormalized, feature-oriented, graph-based, or exposed through a semantic layer. The important decision is not “normalized versus denormalized.” It is whether the representation exposes the right business concepts, relationships, grain and metrics for the workload.
Don’t default to the technique your team already knows. Match the model to the workload.
- Transactional systems → relational modeling
- BI and analytical reporting → dimensional modeling
- High source volatility and historical traceability → Data Vault
- Relationship-intensive use cases → graph-oriented models
- AI and natural-language analytics → governed serving models and semantic layers
AI consumption does not automatically mean denormalization. The right representation depends on the questions the AI system needs to answer, and the business semantics it needs to understand.
Explore how NoSQL and columnar databases support modern data storage, processing, and modeling requirements.
From Data Models to Semantic Intelligence
- 1. Cloud and Lakehouse Modeling:Cloud warehouses changed modeling economics, compute and storage scale independently, so old normalization trade-offs no longer apply. Denormalizing for query simplicity is often cheaper now, but not free: consumption-based pricing means a poorly modeled warehouse shows up directly on the bill.
- Lakehouse architectures blend lake flexibility with warehouse governance, schema-on-read for exploratory data, with a governed, modeled layer on top for anything feeding reporting or AI. The mistake I see most: treating the lake as a dumping ground with no modeling discipline, then wondering why nothing built on it is trustworthy.
2. Semantic layers sit between the physical model and whoever, human or AI agent, is querying it, translating business terms so “active customer” means the same thing to both. A human can catch an ambiguous definition and ask a colleague. An AI agent can’t, it uses whatever the model gives it, confidently. That’s exactly what happened at 2 a.m.: no semantic layer to consult, two conflicting definitions, and the agent picked one without knowing it was choosing.
3. AI-ready data is not simply data that has been flattened into a wide table. It is data whose meaning, relationships, quality, provenance and usage constraints are explicit enough for machines to consume reliably.
That can require different representations for different workloads. A BI workload may need a dimensional model. An ML system may need feature-oriented datasets. A relationship-heavy application may benefit from a graph. An AI analytics agent may need a semantic model that defines metrics, relationships, filters and business terminology.
The common requirement is not a particular schema pattern. It is semantic consistency.
Metadata that once served primarily as documentation for humans increasingly becomes operational context for AI systems. When the grain, definitions and business rules are unclear, an AI system may infer them incorrectly rather than recognizing that the information is ambiguous. Current semantic-model guidance similarly emphasizes explicit descriptions, relationships, metrics, filters and iterative testing for AI-generated queries.
DATA MODEL ≠ SEMANTIC LAYER
Data Model vs. Data Contract vs. Semantic Layer
These concepts are related but solve different problems:
| Concept | Primary question |
|---|---|
| Data Model | What entities, attributes and relationships exist? |
| Data Contract | What does the producer guarantee to its consumers? |
| Data Catalog | What data exists, where is it, and who owns it? |
| Semantic Layer | What does the data mean to the business and its consumers? |
| Governance | Who can use the data, under what rules and constraints? |
The distinction matters because an organization can have a technically valid data model and still have ambiguous business semantics.
A column called customer status may have a perfectly valid datatype and constraint while different teams interpret “active” differently. The technical model is correct; the business meaning is not governed.
Modern data architecture therefore needs these capabilities to work together rather than treating modeling, contracts, semantics and governance as separate disciplines.
Data Contracts and Data Products
A data contract should not be confused with a semantic layer. A contract governs what a producer promises to deliver; a semantic layer governs how consumers understand and use that data. Adoption has moved fast from early-adopter practice to operational standard, because organizations scaling data products found that informal ownership and late stage schema checks don’t hold up once AI agents query data directly.
The retail team’s fix was a data contract between the orders and returns teams: any change to how “active customer” was defined would now break a test, not drift silently into production. Treating your model as a product, with an owner, a defined interface, and an enforced contract, keeps it from drifting out of sync with what’s actually consuming it.
Data Modeling Standards and Process
The conceptual, logical and physical layers remain useful abstractions for designing and communicating data structures. What has expanded is the scope of what needs to be captured around those structures: business definitions, metadata, lineage, ownership, quality expectations, access policies and machine-readable semantics.
In other words, the model increasingly needs to describe not only what the data looks like, but also what the data means and how it can be used.
The modeling process itself hasn’t fundamentally changed, requirements, conceptual, logical, normalization, physical, validation, documentation, implementation, but two steps deserve more weight: cross, team agreement on the conceptual layer, and governance around every change to it. That’s exactly where the retail team’s three–year-old discrepancy lived. Nobody skipped modeling, they skipped agreement, and they skipped treating a definition change as something to review.
Data Modeling Tools
Tooling has shifted toward platforms that integrate directly with cloud data stacks: ER/Studio and Erwin Data Modeler for full CDM/LDM/PDM collaboration, DbSchema Pro across relational and NoSQL, dbt as the near, default for modeled layers with built, in version control and testing, cloud, native catalog tools that bundle modeling with lineage and governance, and Archi or Open ModelSphere for system, level architecture views.
The trend: modeling, governance, and lineage are converging into one toolchain, because treating them separately is exactly how a three–year-old discrepancy survives unnoticed.
Data modeling is just the beginning. Discover how modern data practices and platforms turn well-structured data into actionable intelligence.
Best Practices for Data Modeling
- Model for business questions, not source systems – entities should map to how decisions get made, not to whatever the source system exposes.
- Match the technique to the workload – dimensional for BI, Data Vault for auditability, and wide structures for AI consumption.
- Document the “why,” not just the “what” – record why a grain or relationship was chosen and note known edge cases.
- Treat schema changes as breaking changes – version control and data contracts should prevent structural drift, while semantic changes to metrics, definitions and business rules should receive equivalent review.Build for the business question, not just the producer, design models around the decisions, analytics, ML workloads and AI/agent interactions they need to support.
- Review on a cadence, not a crisis – a model untouched for a year is already accumulating debt. The retail team’s went three.
- Define grain explicitly – every analytical model should make it clear what one row represents. Ambiguous grain is one of the fastest ways to create incorrect joins, metrics and AI-generated queries.
- Make business semantics machine-readable – document definitions, relationships, metrics, filters, ownership and usage constraints in a form that downstream systems and AI tools can consume.
Key Trends Shaping Data Modeling
1. Semantic modeling is becoming a first-class architecture capability
Organizations are increasingly investing in semantic layers that make business meaning, relationships and rules understandable to both humans and machines. MIT CISR’s 2026 research identifies this as increasingly important for enterprise AI initiatives.
2. Data contracts are moving closer to the development lifecycle
Schema, quality, ownership and service expectations are increasingly being treated as explicit interfaces between data producers and consumers rather than informal agreements.
3. AI is changing what “good documentation” means
Descriptions, relationships, metrics, filters and business terminology are no longer only for human readers. AI systems increasingly use them as context when generating queries and interpreting enterprise data.
4. Modeling is becoming iterative
Modern semantic models need to be tested against real business questions, measured for accuracy and refined over time. Current platform guidance explicitly recommends evaluation sets, verified queries and iterative refinement rather than treating the model as a one-time artifact.
5. Different models will coexist
Mature data estates will not converge on one universal modeling technique. Relational, dimensional, Data Vault, graph, feature-oriented and semantic models will coexist, each serving different workloads.
Key Takeaways
- Data modeling remains foundational, but its role has expanded.
- Conceptual, logical and physical models still matter in modern cloud architectures.
- Modeling technique should follow workload, not organizational habit.
- Business semantics are becoming as important as physical schema.
- Data contracts govern what producers promise; semantic layers govern how consumers understand the data.
- For AI, the goal is not simply more data. It is data whose meaning, relationships, quality and constraints are explicit enough for machines to use reliably.
By leveraging our knowledge and experience, your business can confidently embrace scalable data management systems. Your business can also implement strong data governance practices.
With our support and guidance, your organization can navigate the complex data landscape, foster innovation, and ultimately achieve success in this ever-evolving digital age.
Contact us to see how we transform raw data with big data analytics solutions.