
Highlights
GraphQL is changing how applications interact with APIs by giving clients greater control over the data they request. From understanding how it works to exploring its differences from REST, this blog covers the fundamentals of GraphQL API architecture, schemas, queries, resolvers, and mutations. It also looks at it over HTTP, security best practices, federation, and how it can support AI agents. Whether you are evaluating GraphQL for a new application or working with an existing API, understanding its execution flow, flexibility, scalability considerations, and security requirements can help you make more informed architectural decisions.
That nagging question, that doesn’t allow you to rest till you put pen to paper – or in this case – keys to MS Word. I have been asked this very question multiple times, and I thought it was best to put it out there for all to know.
Let me start by saying that the first word in your GraphQL vocabulary notebook should be API. Application Programming Interface (API) is a software interface that exposes backend data and application functionality to various client applications and hence APIs are treated more like product than code. Modern APIs adhere to standards like HTTP and REST. When it comes to API development, we are more likely to implement REST APIs which is proven or in practice a very viable option. However, GraphQL seems to be changing this very notion.
What is GraphQL?
Ask and you shall receive (data)
GraphQL, a query language for API and runtime uses existing data to fulfill queries. It provides a specific type system that can help you define data, make queries, change or subscribe to data updates by using a very specific query format. GraphQL enables declarative data fetching i.e. the shape of the received data exactly as requested. So yes, if you know how to ask, then you shall receive data which is tailored to match your exact requirements.
GraphQL provides an understandable description of data and flexibility to clients to ask for what they want, which makes it easier for GraphQL APIs to evolve over time and make efficient use of the network bandwidth. GraphQL supports multiple transport protocols like HTTP, MQTT, and WebSockets.
How Does GraphQL Work?
A GraphQL API works through a clear execution flow that connects the client’s request to the data returned by the GraphQL server. The process can be broken down into five steps:
1. The schema defines what can be requested
Every GraphQL API starts with a GraphQL schema, which defines the data and operations available to clients. It specifies the GraphQL types, fields, queries, mutations, and relationships that can be requested.
The schema acts as a contract between the client and the GraphQL server. This means a client can only request fields and operations defined by the schema.
2. The client sends an operation
The client sends a GraphQL query to the GraphQL endpoint, specifying exactly what data it needs. Unlike traditional REST APIs, where the server determines the structure of the response, GraphQL allows the client to define the shape of the requested data.
The operation can be a query for fetching data, a mutation for changing data, or a subscription for receiving real-time updates.
3. The server parses and validates the operation
When the GraphQL server receives the request, it first parses the operation and validates it against the GraphQL schema. It checks whether the requested fields, arguments, and types are valid.
If the operation does not match the schema, the server returns an error without executing the request. If it is valid, execution moves to the next step.
4. Resolvers fetch the data
Once the GraphQL query is validated, the server executes the relevant GraphQL resolver for each requested field. A resolver determines where the data comes from and how it should be retrieved.
The data may come from a database, microservice, another API, or another data source. Resolvers can also handle nested fields, allowing a single GraphQL query to retrieve related data.
5. The response mirrors the request
Finally, the GraphQL server returns a response that follows the same structure as the client’s request. If the client asks for specific fields and nested objects, the response contains those requested fields in the corresponding structure.
This request-and-response flow is what gives GraphQL APIs their flexibility: clients ask for the data they need, and the server returns data in the shape they requested.
The schema, queries, and resolvers that make this flow possible are covered in detail in the GraphQL Details section below.
GraphQL vs REST
REST (Representational State Transfer) is a software architectural style that defines a set of constraints such as statelessness, cacheability, layered systems, and a uniform interface. REST APIs expose resources through different endpoints, while GraphQL allows clients to request related data through a single GraphQL API.
One important difference between a GraphQL vs REST API approach is how data is fetched.
In RESTful APIs, a representation of a resource is created by the server, which in turn responds to a client. If the client wants something specific with connected entities, representation can become difficult.
For example, a GET API for tweets may return tweet_id and tweet_content. If a client also wants the author of each tweet, it may need to make another server request.
This can cause under-fetching, where the client has to make additional requests to obtain the information it needs.
Alternatively, an existing REST API could be modified to include author information. This can cause over-fetching, as not all clients require that additional attribute.
Creating a new REST endpoint for every frontend requirement can also increase development effort.
GraphQL addresses these situations by allowing the client to request only the required fields, including nested and related data, through a GraphQL query.
The choice between GraphQL vs REST therefore depends on the application. REST remains a widely used approach, while GraphQL can be useful when applications have complex relationships between data and clients need flexibility in how data is fetched.
Still Choosing Between REST and GraphQL?
Compare their key differences, pros, cons, and features in this quick cheat sheet.
GraphQL over HTTP
GraphQL itself is transport-agnostic, but it is most commonly served over HTTP.
The way GraphQL communicates over HTTP can be understood through how clients send requests, how servers return responses, and how real-time subscriptions maintain connections.
1. Requests
- POST is the standard method. The body is JSON containing query, and optionally variables and operationName, with the header Content-Type: application/json.
- GET sends the same parameters in the URL and suits cacheable queries. Mutations should not be executed over GET.
2. Responses
The response is JSON with a data field, an errors field, or both. A request that executes but has field-level errors typically returns 200 OK with an errors array, so clients should check the response body and not rely on the status code alone. Malformed requests return 400 Bad Request. The specification recommends the media type application/graphql-response+json, though many servers still use application/json.
3. Subscriptions
Queries and mutations fit HTTP’s request-response model. Subscriptions keep a connection open and are commonly implemented over WebSockets or Server-Sent Events.
GraphQL API Security Best Practices
A GraphQL API gives clients flexibility, but that flexibility needs to be controlled. GraphQL API security should therefore be considered while designing the schema, resolvers, and GraphQL server.
Some important GraphQL API best practices include:
- Use authentication and authorization: Verify users before allowing access to the GraphQL endpoint and apply authorization rules at the appropriate field or resolver level.
- Limit query depth: Deeply nested GraphQL queries can consume significant server resources. Depth limits can help prevent excessively complex requests.
- Apply pagination: Fields that return large lists should support pagination so clients cannot request an overwhelming number of records at once.
- Control query complexity: Complexity limits can prevent expensive GraphQL queries from consuming excessive resources.
- Protect mutations: GraphQL mutations should validate inputs and enforce authorization before changing data.
- Avoid exposing unnecessary schema details: Introspection and schema exposure should be considered carefully in production environments.
- Use batching and caching carefully: Data loaders can reduce repeated backend calls, while request-level caching can help improve efficiency.
Pagination is particularly important for both performance and security. Fields that may return long lists should accept arguments such as limit and next to narrow the search.
What Is GraphQL Federation?
GraphQL federation is an architectural approach that allows multiple services to contribute to a single GraphQL API. Instead of maintaining one large schema and one underlying service, different teams or services can own parts of the overall GraphQL schema.
How it works
- Each service publishes its subgraph schema.
- The subgraphs are composed into one supergraph schema.
- A router (or gateway) receives client queries, splits them into parts, fetches each part from the owning subgraph, and merges the results into one response.
A federated GraphQL architecture can expose related data from different services through a unified GraphQL endpoint. For example, user information, products, payments, and orders may be managed by separate services while still being accessible through one GraphQL API.
This approach can help teams organize ownership around individual domains while providing clients with a consistent way to query related data.
GraphQL federation becomes particularly useful as the number of entities and relationships in an application grows.
When to use GraphQL?
You use GraphQL when you want to:
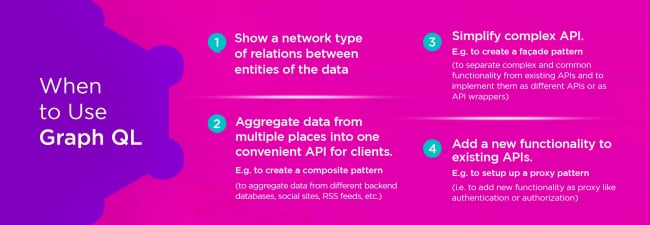
- Give clients control over the data they receive.
- Reduce over-fetching and under-fetching.
- Fetch related data through nested GraphQL queries.
- Work with applications that have many entities and relationships.
- Provide one API for different client requirements.
- Support evolving APIs without requiring frequent versioning.
Explore more about REST, scalability, and AI-powered APIs in these blogs
GraphQL Ecosystem
GraphQL Details
Schema, queries, and resolvers are the three building blocks of GraphQL.
Schema
GraphQL uses a strong type system to define API capabilities. The types are declared in a schema using the Schema Definition Language (SDL), which acts as a contract between client and server. Because both sides know the data structure, frontend and backend teams can work in parallel. Frontend teams can mock the agreed structure and switch to the real API once the server is ready. The schema also validates every incoming query.
Queries
Queries fetch values and reduce over-fetching. They support nested fields and arguments.
- Request an item from the server
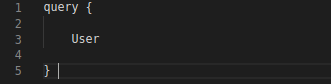
- Ask for specific fields
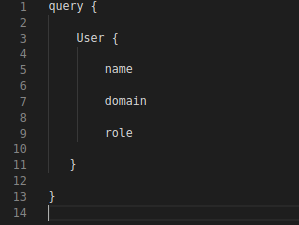
- Fetch arrays using query fields
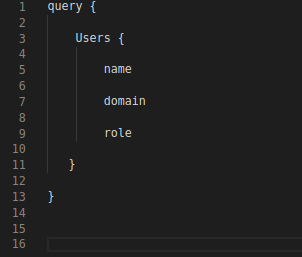
- Fetch a specific user by passing an id argument, which can be a dynamic parameter

Resolvers
The API schema and database schema are decoupled in GraphQL. A resolver processes an incoming query by defining how and where to fetch the data for a given field, and even subfields can have resolvers. Resolvers that update data are called mutation resolvers.

Best Practices
Input object type for mutations
Create and update operations are mutations. An input object type keeps them simple and easier to extend later. Apply a non-null modifier so the payload is never null.
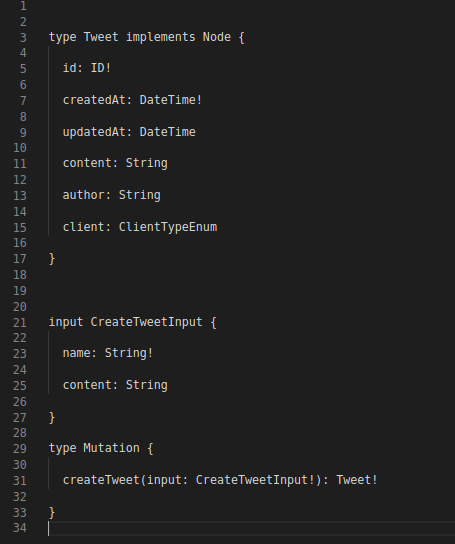
Schema design with interfaces
Interfaces and unions standardize the schema and reduce complexity by abstracting a group of objects into one entity. For example, User, Tweet, and Comment all repeat id, createdAt, and updatedAt. An interface makes those fields consistent.


Interfaces also let you replace several queries with one item query. Any type implementing the Node interface can be fetched this way, since id is a global identifier.
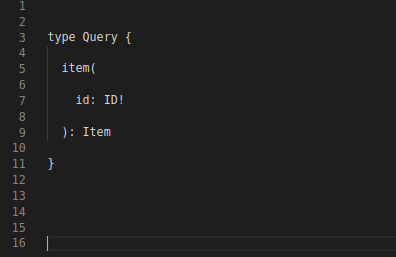
A client can get any item by calling same query.
For example, to get tweet, it can call for:
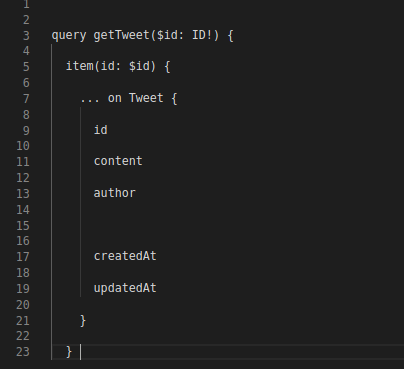
To get a user, you could ask for:

Returning affected objects as a result of mutations
A good mutation returns the changed record, so the client cache and UI stay consistent. For example, createComment and updateComment return Comment!, letting the UI append or refresh the comment.
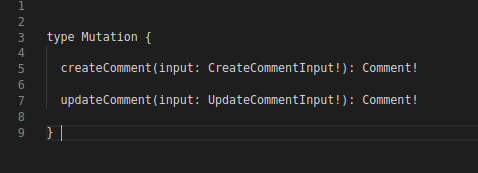
Nesting objects in queries
Returning only an author ID forces an extra query. Nesting the output type lets one query fetch everything, which helps caching and batch loading, especially on slow networks.
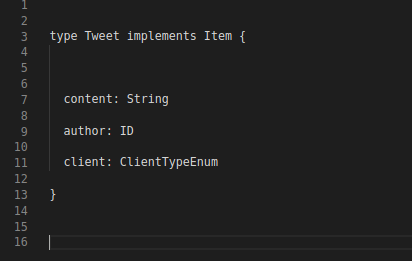
These types can be reused and ID can be substituted with type. It is preferable to nest the output type in GraphQL, since one can call everything in a single query helping to cache and in batch data loading.

Versioning
REST clients have little control over returned data, so API changes can break them, which is why versioning is used. With GraphQL, you add new types or fields without affecting existing clients, so a new version is rarely needed.
Null type mapping
Every GraphQL field is nullable by default. If a database fails or a field’s authorization fails, only that field returns null instead of the whole request failing. Non-null types are stricter: if the field fails, the null propagates to the parent field. List the areas that could fail and decide whether null is acceptable for each.
Schema design: consistent naming convention
Use camelCase for fields, PascalCase for types, and ALL_CAPS for enum values. Name input types as (Action)(Type)Input, such as CreateTweetInput, and keep patterns like pagination consistent.
Paginated lists
Paginate any field that can return long lists to protect performance and guard against exhaustion attacks. Fields typically accept arguments like limit and next. The Connections convention supports richer pagination, and tools like Relay and AWS AppSync support it.
Batching & caching
Without care, resolvers can load the same data repeatedly. A data loader batches requests over a short window into a single backend call. It caches results until told otherwise, so create a new instance per request to de-duplicate within one query but not across users.
Enable GZIP
GraphQL usually responds in JSON, though the spec doesn’t require it. Since JSON is text, it compresses well. Enable GZIP in production, and have clients send Accept-Encoding: gzip.
Future schema updates
Plan for change from the start by adding output and input types as needs arise, which avoids breaking changes. Schema generators are useful for prototyping, but avoid relying on them for complex schemas.
GraphQL and AI Agents
GraphQL can also support applications built around AI agents. An AI agent may need information from multiple connected data sources while selecting only the fields relevant to a particular task.
A GraphQL API can give an agent a typed schema that describes available data and operations. The agent can construct a GraphQL query to request specific information rather than retrieving an entire resource. Agents can connect to these capabilities through an MCP server that exposes approved GraphQL operations as tools, allowing the agent to interact with data through a controlled interface.
Because agents can generate their own queries, GraphQL API security becomes especially important. Least-privilege access, depth and complexity limits, and persisted operations can help control what agents can request and how much server resources they can consume. Instead of exposing the entire GraphQL schema, applications can also provide agents with a limited schema or a set of approved operations relevant to their tasks.
GraphQL mutations can allow an agent to perform approved actions, while authorization and query controls remain important when agents are allowed to access or modify data.
As AI applications become more connected to structured business data and services, GraphQL can provide a consistent interface for agents to discover and interact with that data.
GraphQL is a powerful tool and will perhaps prove extremely handy in your upcoming project.
It is an important architectural decision to take, so make sure you assess if your API is best suited for GraphQL. If you have fewer entities and relationships across the entities, then maybe not. But if there are scores and scores of entities you have to deal with in your application, users, items, payments, orders, and so on and so forth, then look no further than GraphQL.
The right choice may not always be the best choice, but if you ask the right questions, the answers may lie with GraphQL, because the core belief of GraphQL is ‘ask and it shall answer’.
Contact us at Nitor Infotech if you would like to know more about our services or know how we can help you implement modern APIs the GraphQL way.